Cloud Bursting for AI Workloads
Reduce GPU idle costs by running steady baseline capacity and bursting spikes to cloud; use spot GPUs, queue-led autoscaling and region controls.
Read moreBlog posts in the Cloud Optimization category
Reduce GPU idle costs by running steady baseline capacity and bursting spikes to cloud; use spot GPUs, queue-led autoscaling and region controls.
Read more
Ten practical steps to cut hybrid cloud spend: centralise visibility, rightsize compute, tier storage, curb egress and assign ownership.
Read more
Remove avoidable cross-cloud distance, scale on real signals, and unify observability to stop multi-cloud slowdowns.
Read more
Compare seven AI cloud-cost forecasting tools for finance, engineering and Kubernetes use cases.
Read more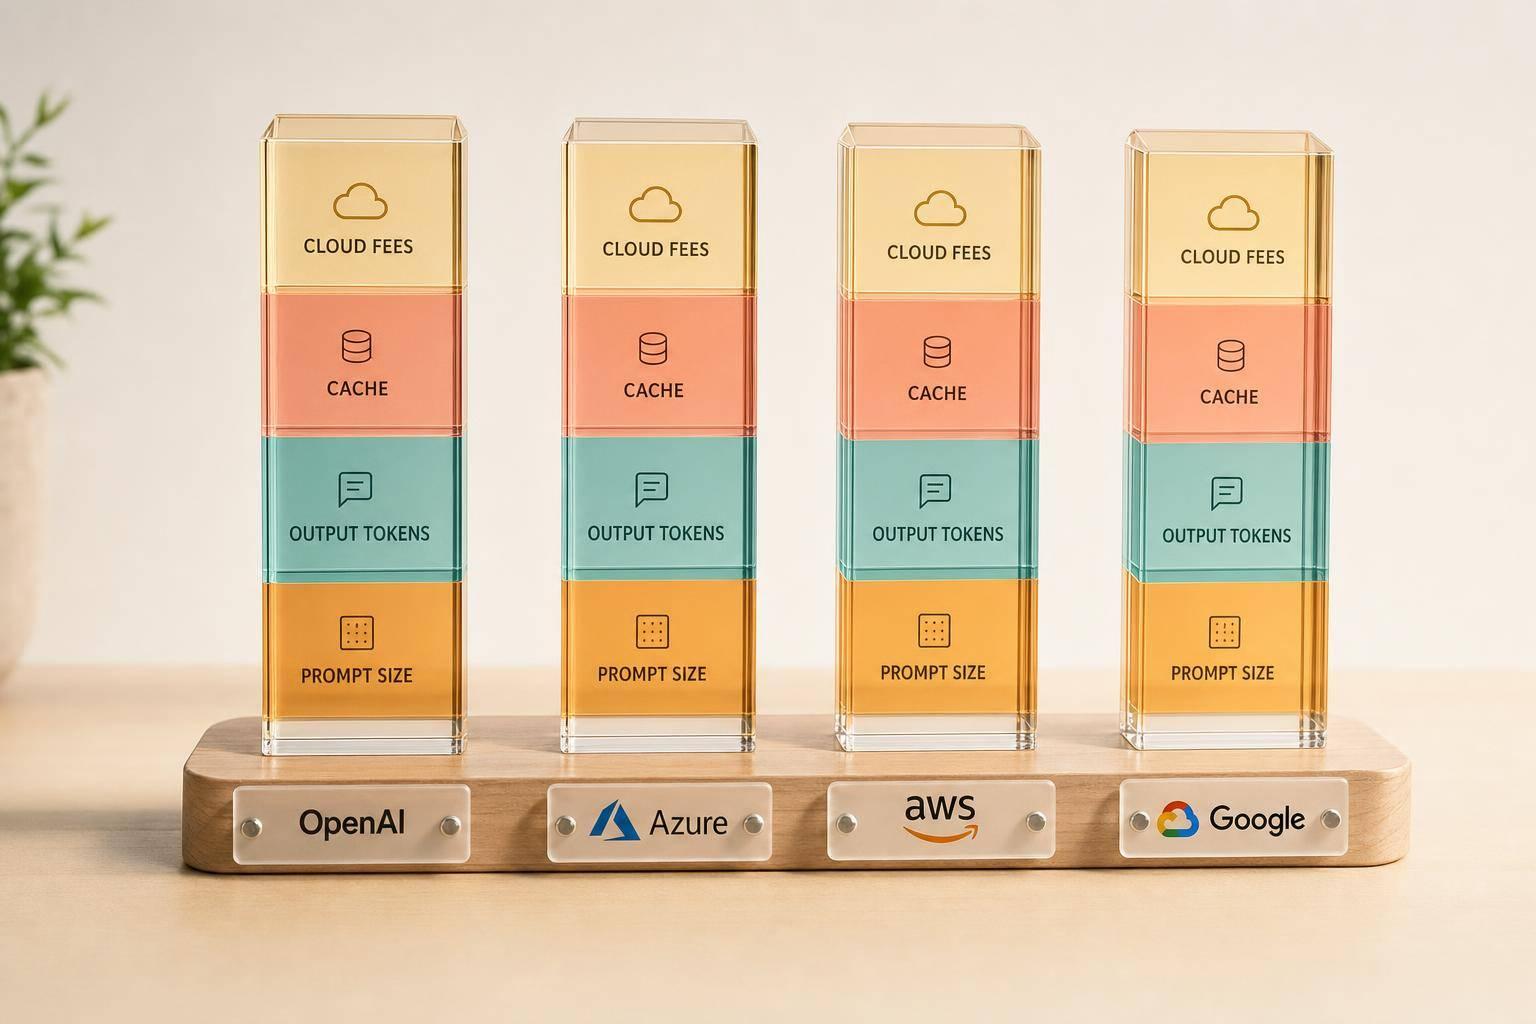
Measure LLM costs by real workloads - prompt size, output, cache and cloud fees usually decide the monthly bill.
Read more
Compare 10 cloud SLA monitoring tools by uptime checks, alerting, latency views and pricing to find the right fit for your DevOps team.
Read more
Send Azure DevOps audit logs to Sentinel for longer retention, alerts and joined investigations; compare ingestion paths and setup checks.
Read more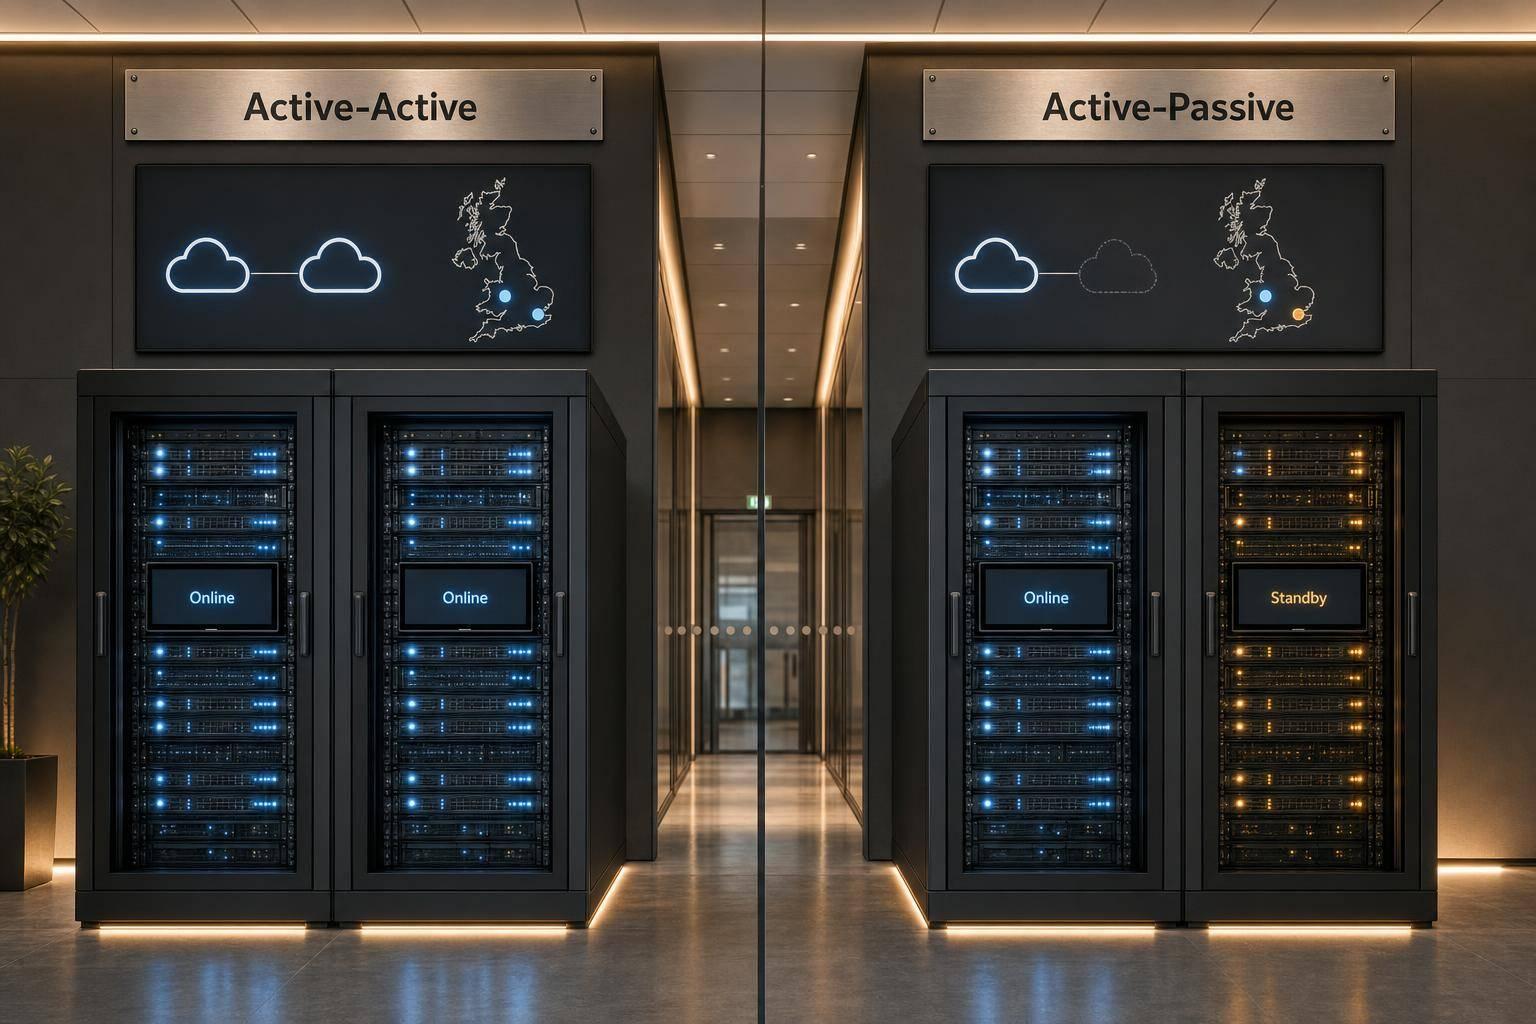
Compare active-active and active-passive multi-cloud Kubernetes: cost, RTO/RPO, data consistency and team impact for UK organisations.
Read more
Compare trend, seasonality, release-driven and AI forecasting to keep cloud spend within actionable error ranges.
Read more
Instrument Kubernetes with OpenTelemetry: six end-to-end tracing patterns, propagation rules, Collector options and common break points.
Read more
Compare cost‑optimised, performance‑optimised, balanced and static AI allocation strategies to align latency SLOs, utilisation and spend.
Read more
Model cloud spend in GBP using cleaned billing, driver-based forecasts and four reusable scenarios to defend budgets.
Read more