Edge and Multi-Region: Autoscaling Strategies
Hybrid autoscaling is essential for edge and multi-region systems—combine predictive forecasts with reactive triggers to cut downtime and meet strict SLAs.
Read moreBlog posts in the Cloud Optimization category
Hybrid autoscaling is essential for edge and multi-region systems—combine predictive forecasts with reactive triggers to cut downtime and meet strict SLAs.
Read more
Compare seven tools to monitor and reduce network latency, covering features, scalability and pricing—from free tests to enterprise monitoring.
Read more
Encrypt IoT data across the hybrid cloud lifecycle — device, transit, storage and processing — using TLS/AES, hardware key storage and automated UK GDPR compliance.
Read more
Practical steps to control hybrid cloud scaling costs: monitor spend, rightsize resources, automate scaling, use reserved and spot pricing, and reduce data transfer.
Read more
Tie AI autoscaling to costs and performance: use predictive scaling, workload tiering, SLOs and budget guardrails to cut GPU spend by 30–50%.
Read more
Audit usage, right‑size resources, automate scaling and enforce governance to cut cloud costs without reducing reliability.
Read more
Avoid common workflow monitoring mistakes that inflate costs and slow deployments. Prioritise key metrics, refine alerts and automate cost controls.
Read more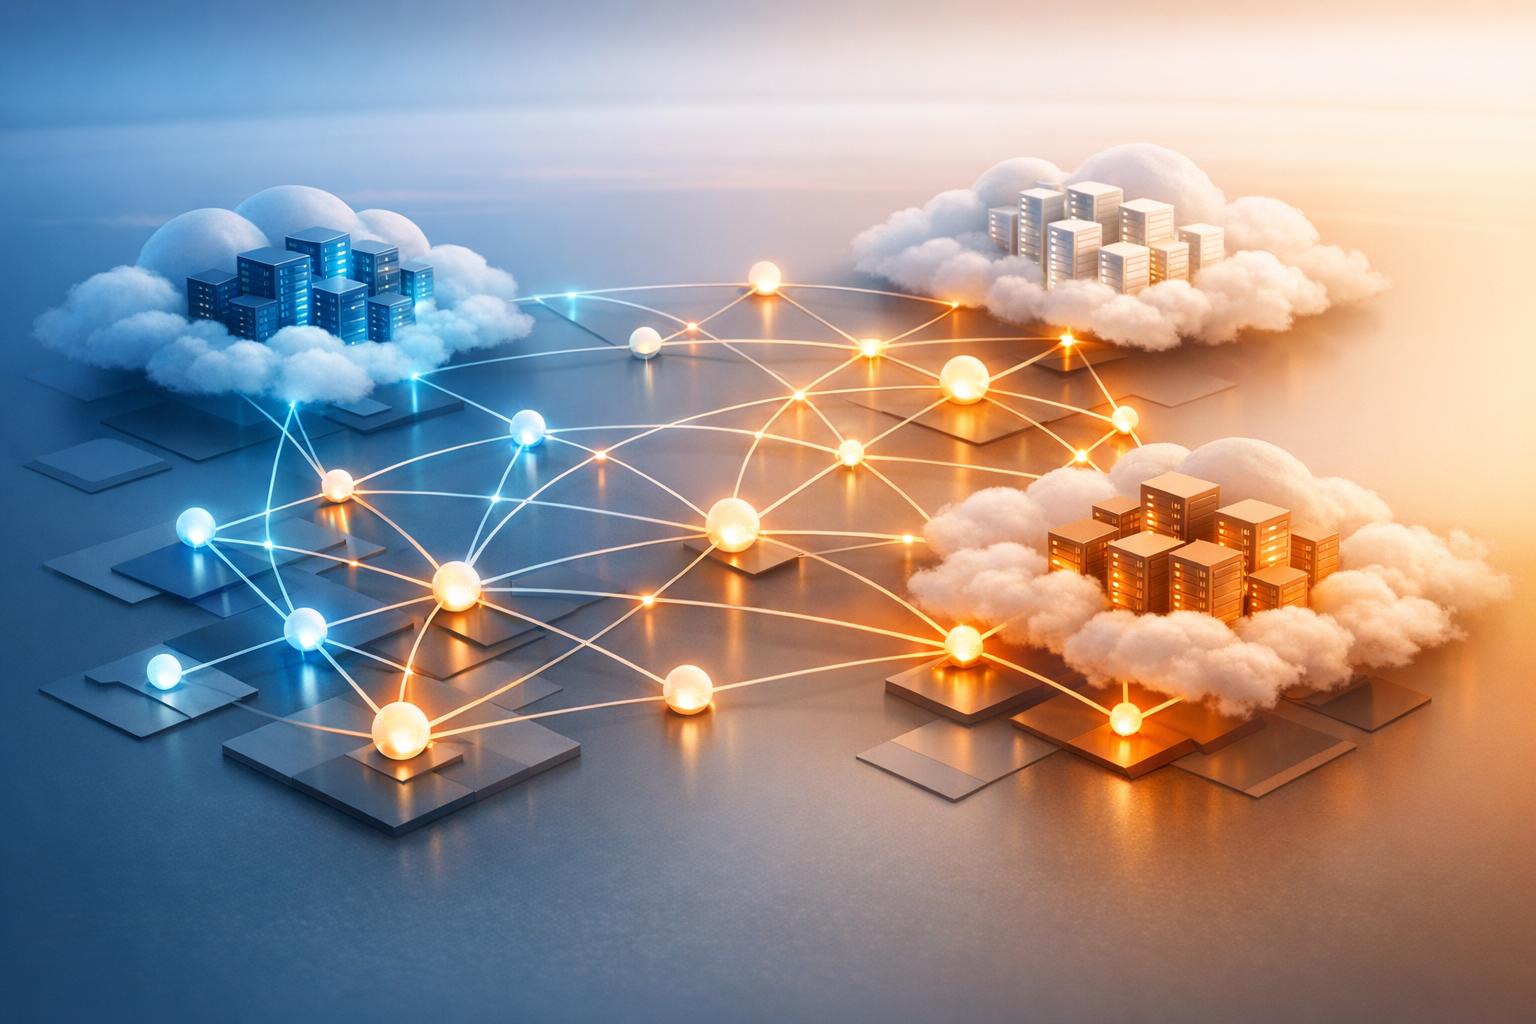
Spot instances can cut multi‑cloud compute costs by up to 90% using spare capacity, automation and a mixed capacity strategy while managing interruption risk.
Read more
Guide to testing a service mesh: validate configs, verify traffic routing and resilience, use observability, benchmark performance and add checks to CI/CD.
Read more
Cut cloud analytics costs up to 90% by running fault‑tolerant workloads on spot instances while protecting data with external storage and mixed on‑demand strategies.
Read more
Compare total cost of ownership for open-source and proprietary CI/CD — licensing, infrastructure, maintenance, and when each option saves UK teams money.
Read more
Five CI/CD metrics—deployment frequency, lead time, change-failure rate, MTTR and pipeline duration—to spot bottlenecks, cut costs and boost developer productivity.
Read more