Graceful Degradation in Microservices: Key Patterns
Keep core microservice functions running during failures using circuit breakers, fallbacks, timeouts, bulkheads and async workflows.
Read more
Keep core microservice functions running during failures using circuit breakers, fallbacks, timeouts, bulkheads and async workflows.
Read more
Use driver-based models, unit economics and TCO to reduce cloud forecast variance and align costs with business metrics.
Read more
Use namespace design, quotas, labels and automation to improve cost visibility, right-size resources and cut Kubernetes spend.
Read more
Prevent zero-trust enforcement failures in multi-cloud: unify identity, segment workloads, boost visibility and roll out policies gradually.
Read more
Practical methods to forecast usage-based cloud costs using historical data, seasonality, predictive models and multi-cloud normalisation.
Read more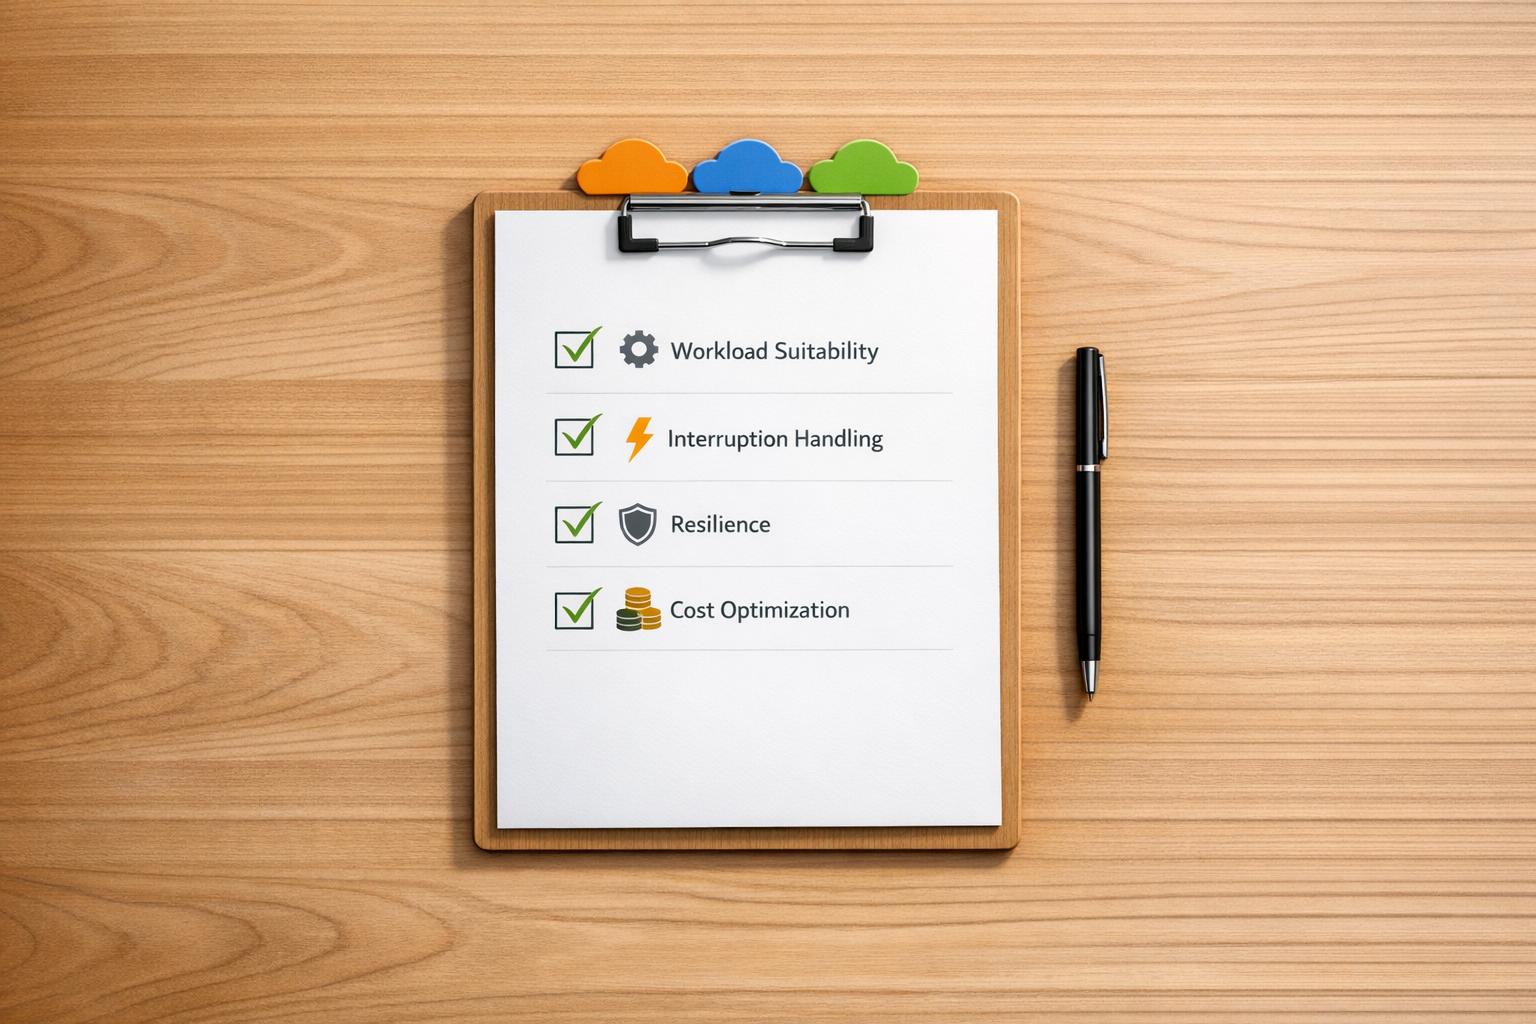
Checklist for running spot instances on AWS, Azure and GCP: workload suitability, interruption handling, resilience and cost optimisation.
Read more
Commit to proven baseline compute, layer RIs and Savings Plans, and keep 20–40% on‑demand to balance savings and flexibility.
Read more
How metrics and logs drive observability costs and practical steps to cut spend: limit cardinality, filter logs, and use tiered storage.
Read more
Layered automated validation ensures data completeness, accuracy and business parity during migration while reducing validation effort.
Read more
Federated Kubernetes lets you treat multiple clusters as one, trading added complexity for cross-region resilience, compliance and burst-to-cloud capacity.
Read more
Practical guidance on standardised pipelines, ownership, automation and governance for secure multi‑cloud CI/CD collaboration.
Read more
Compare AWS SageMaker, Azure ML and GCP Vertex AI for framework support, tooling, cost and integration to pick the right cloud for ML.
Read more