AI Pilot vs Production: How Decision Gates Differ
Pilot success isn’t permission to launch; satisfy four gates—test coverage, user exposure, support ownership and failure limits—before production.
Read moreBlog posts in the Risk Management category
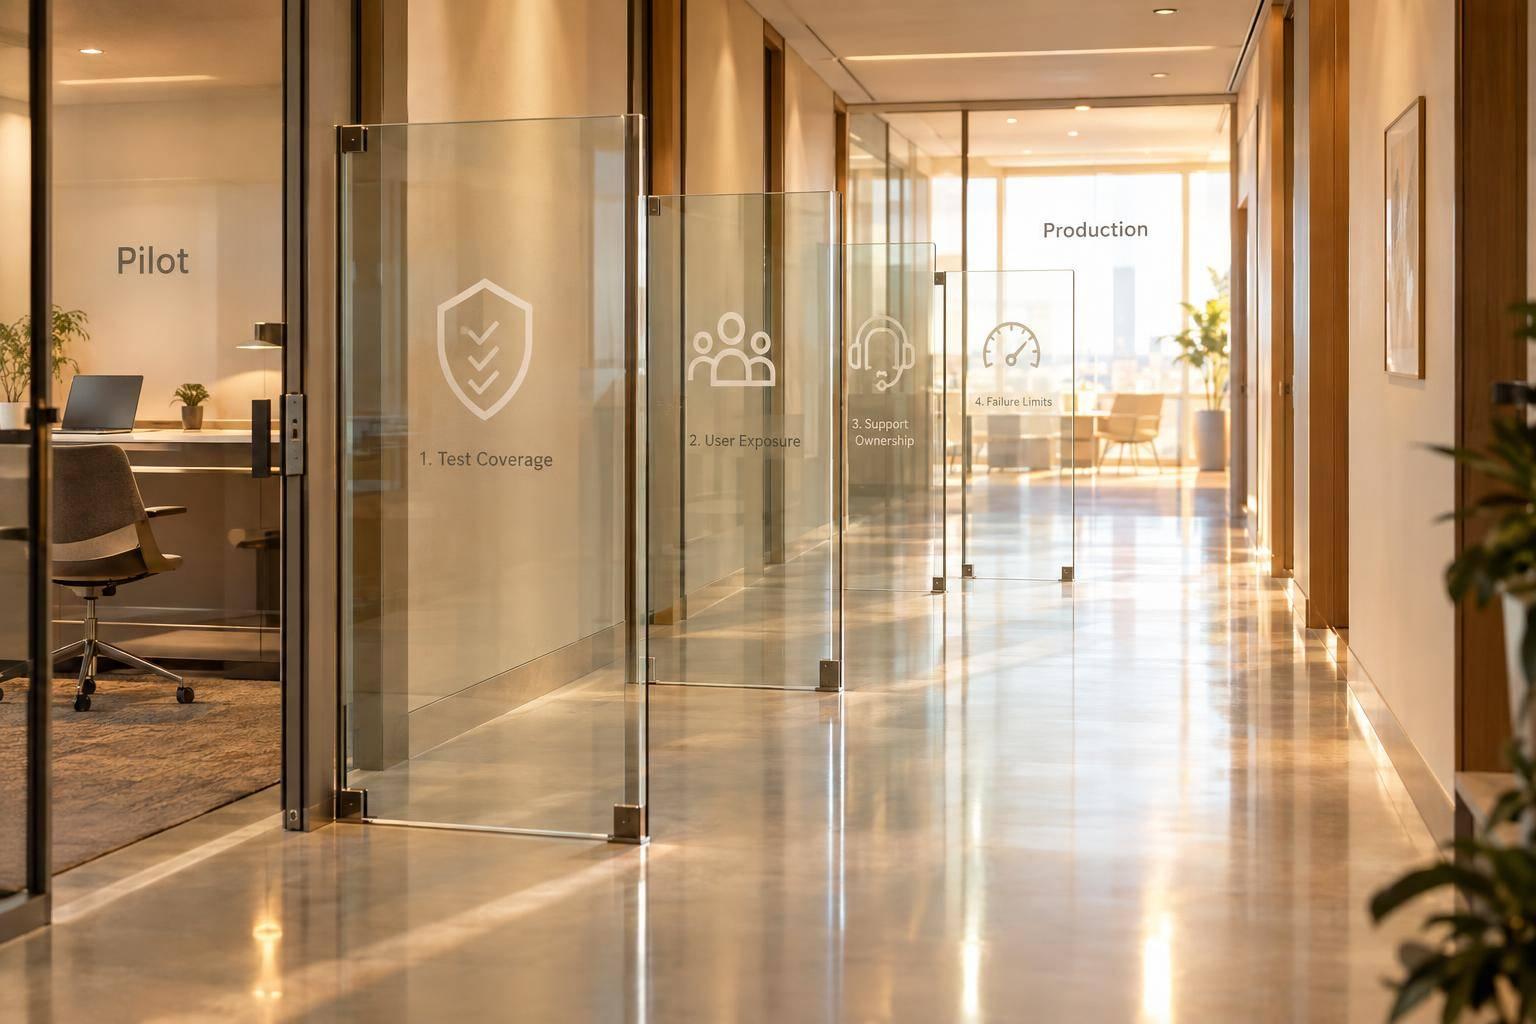
Pilot success isn’t permission to launch; satisfy four gates—test coverage, user exposure, support ownership and failure limits—before production.
Read more
Calibrate RAG abstention thresholds with retrieval, evidence coverage and uncertainty, using error costs to minimise business loss.
Read more
Four-step method to craft evidence-only prompts: cite sources, expose gaps, ask one clarifying question or abstain when unsupported.
Read more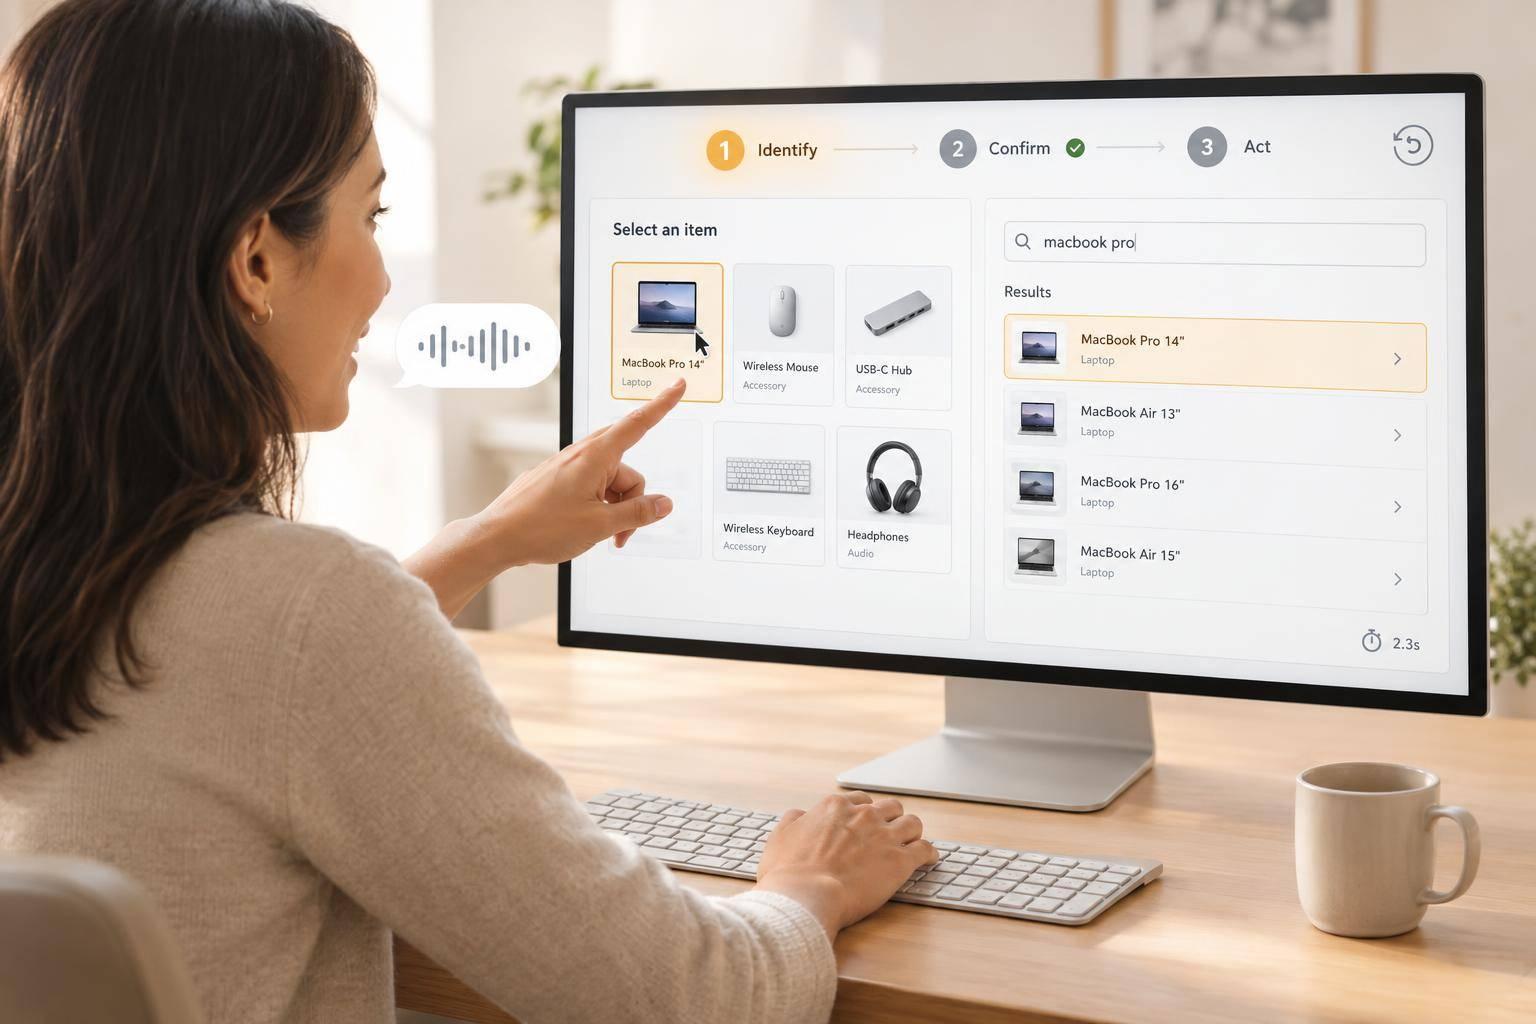
Compare speech+pointing and text for object selection; use identify–confirm–act tests to measure accuracy, time, accessibility and recovery.
Read more
Start with stochastic consensus; escalate to multi-agent debate only when verified critique justifies the extra token cost, latency and risk.
Read more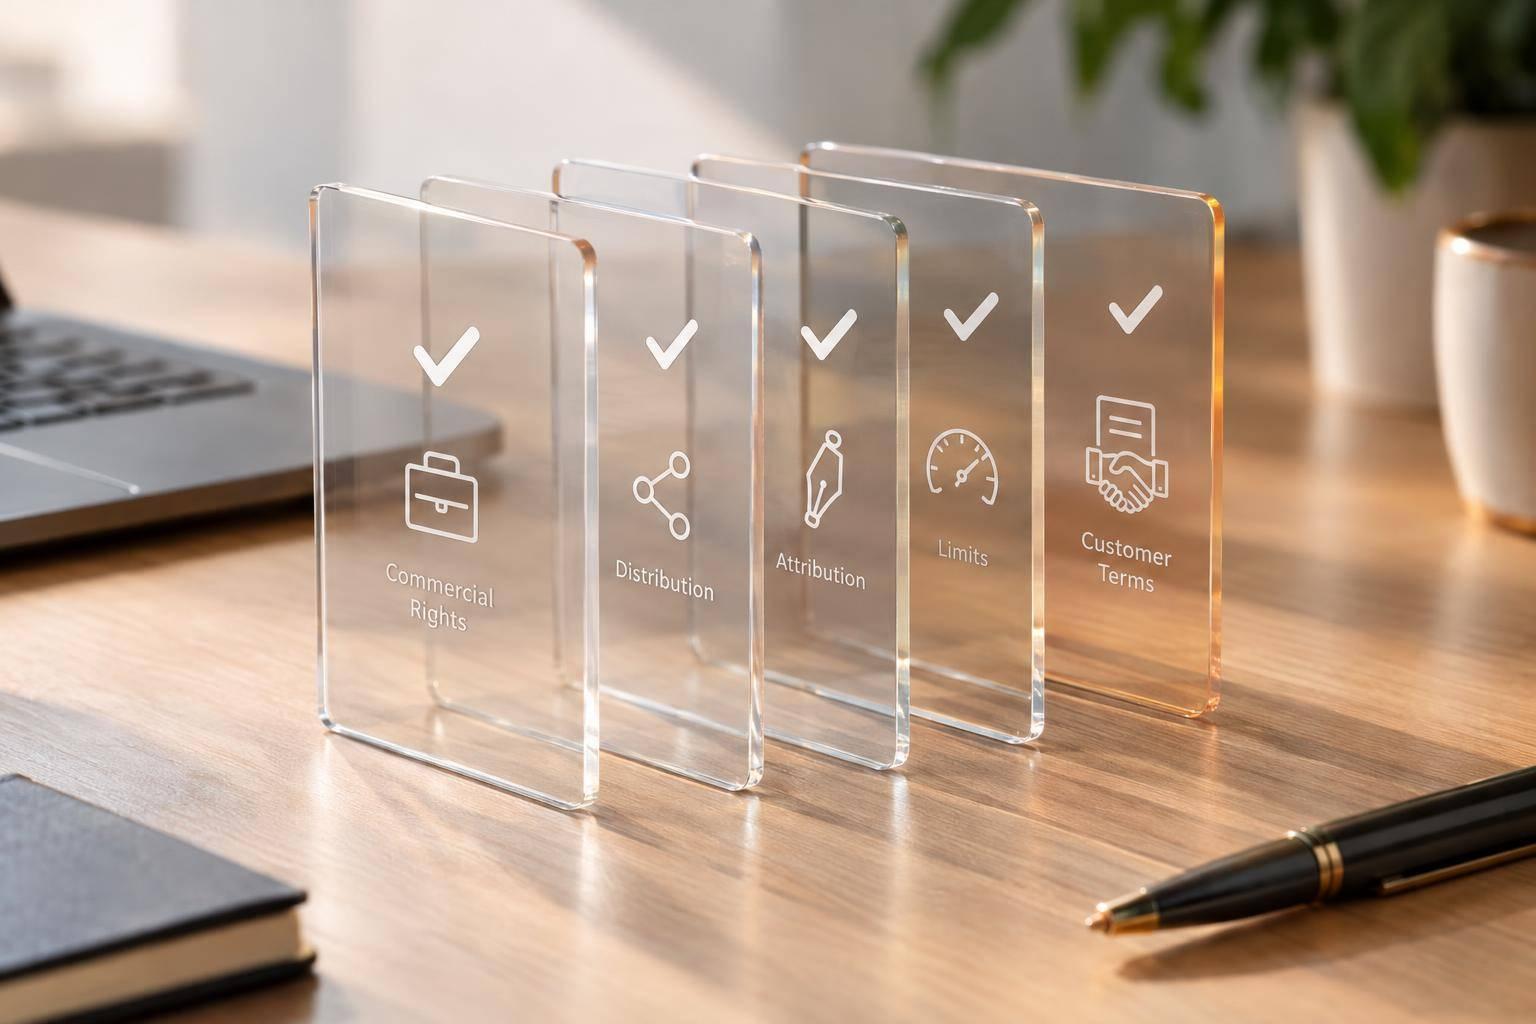
Five licence checks to confirm commercial rights, distribution, attribution, limits and customer terms before selling fine-tuned AI models.
Read more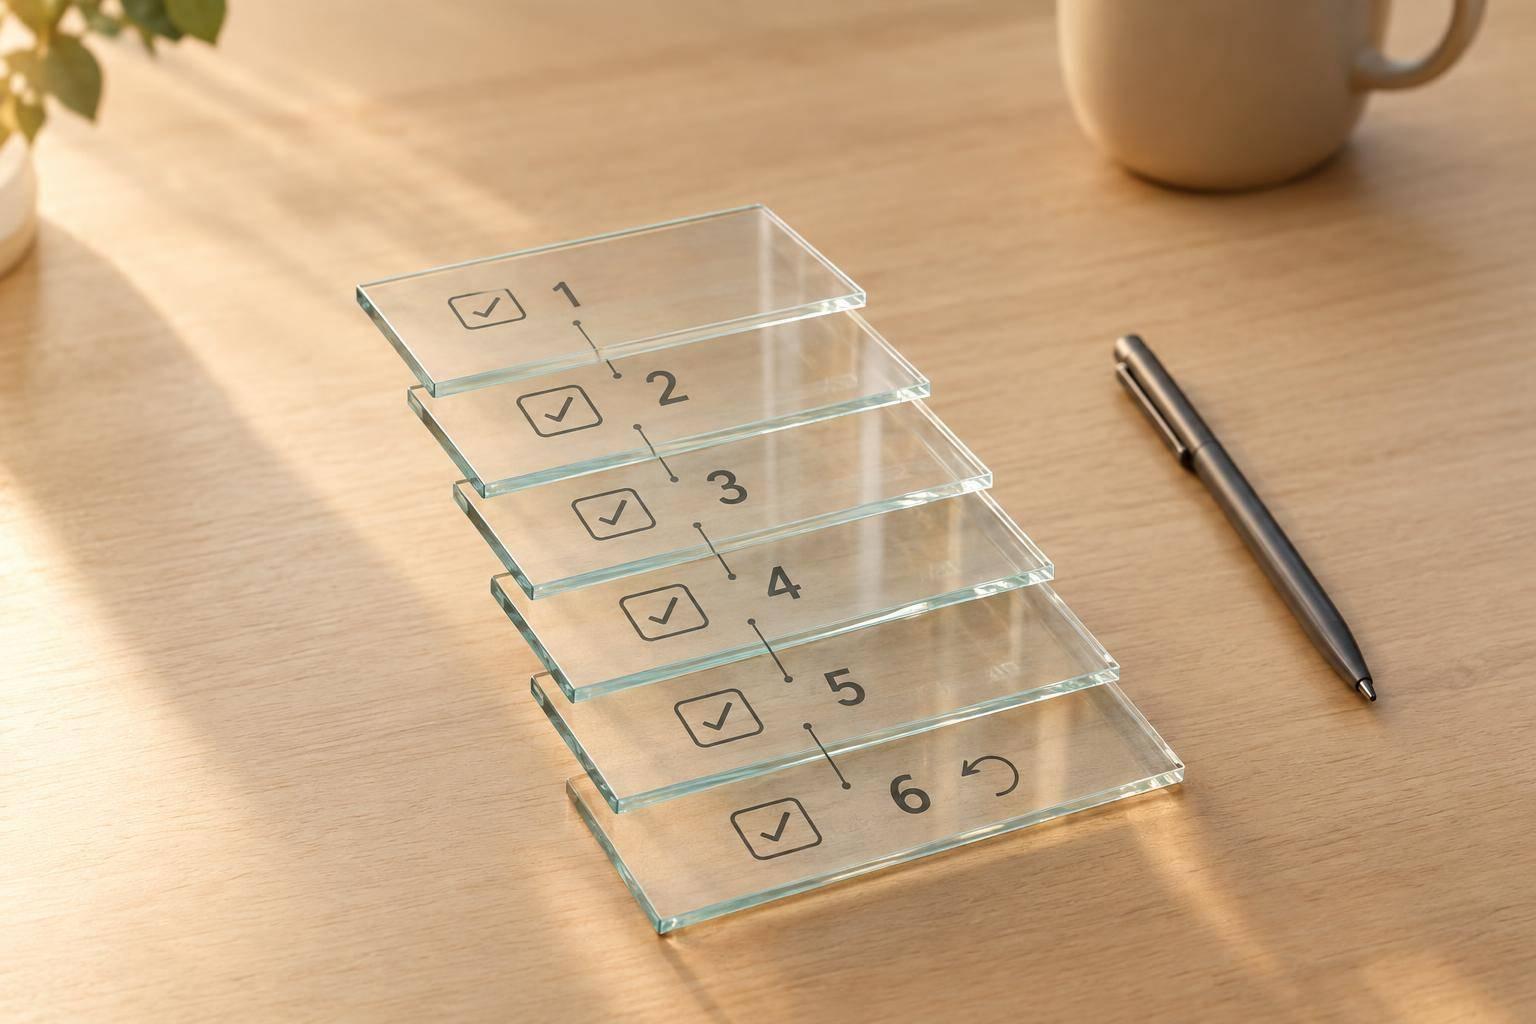
Six-step checklist for LLM SDK upgrades: map breaking changes to apps and owners, validate requests/responses; rehearse rollout and rollback.
Read more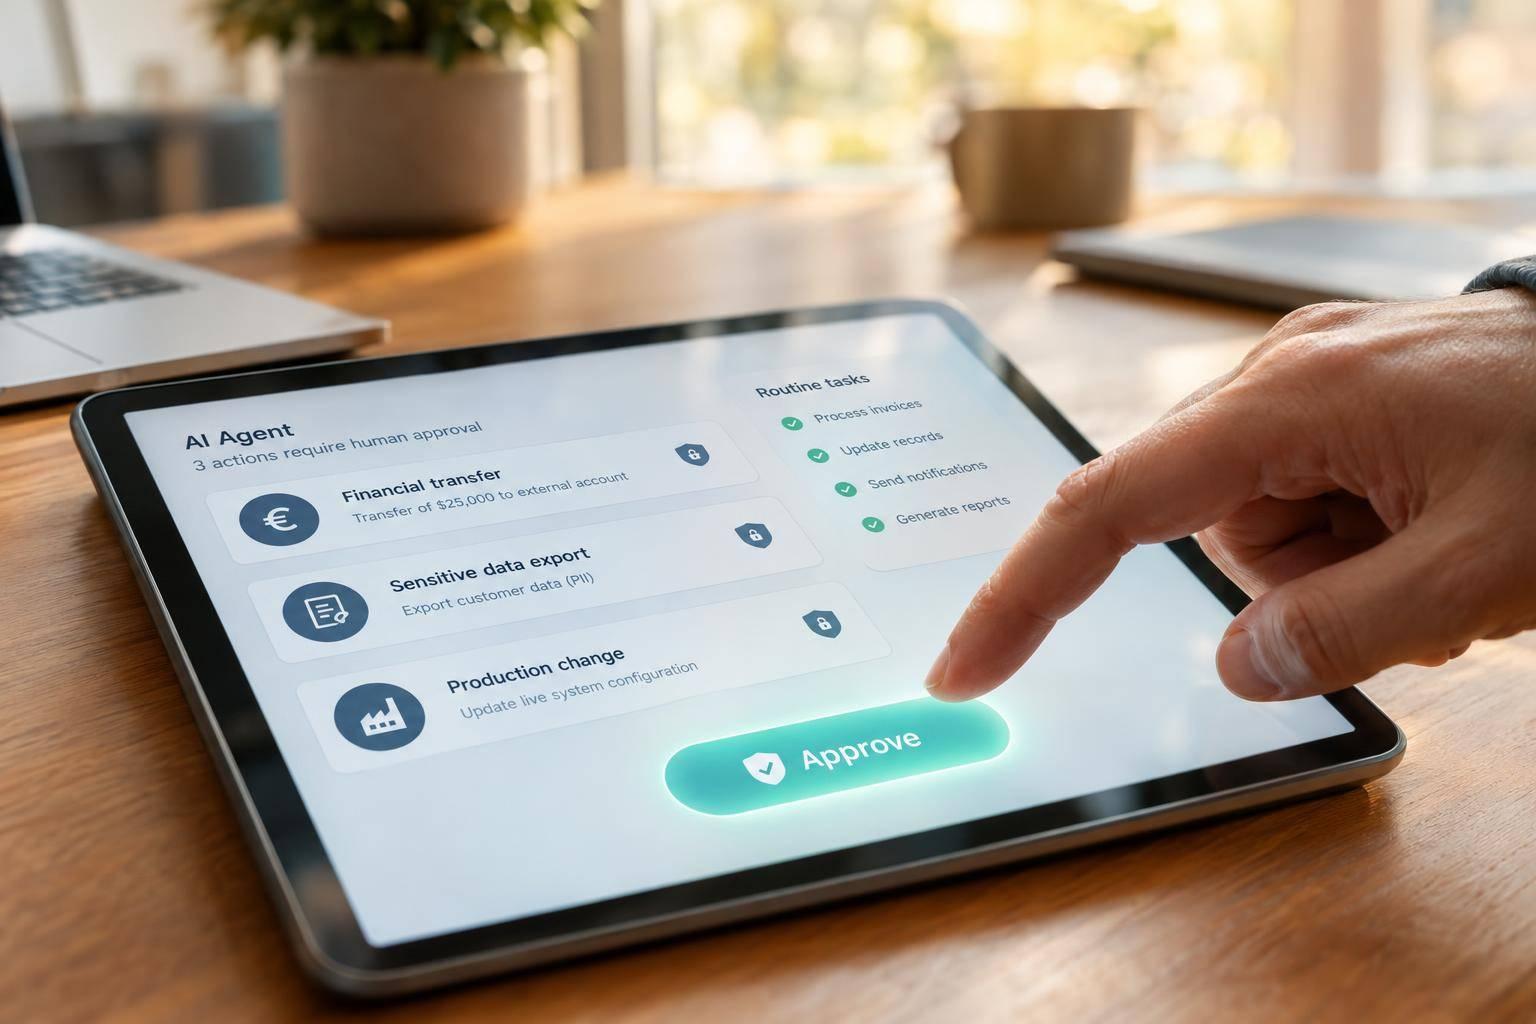
Pause AI agents for human approval on financial transfers, sensitive-data exports and irreversible production changes; automate low-risk tasks.
Read more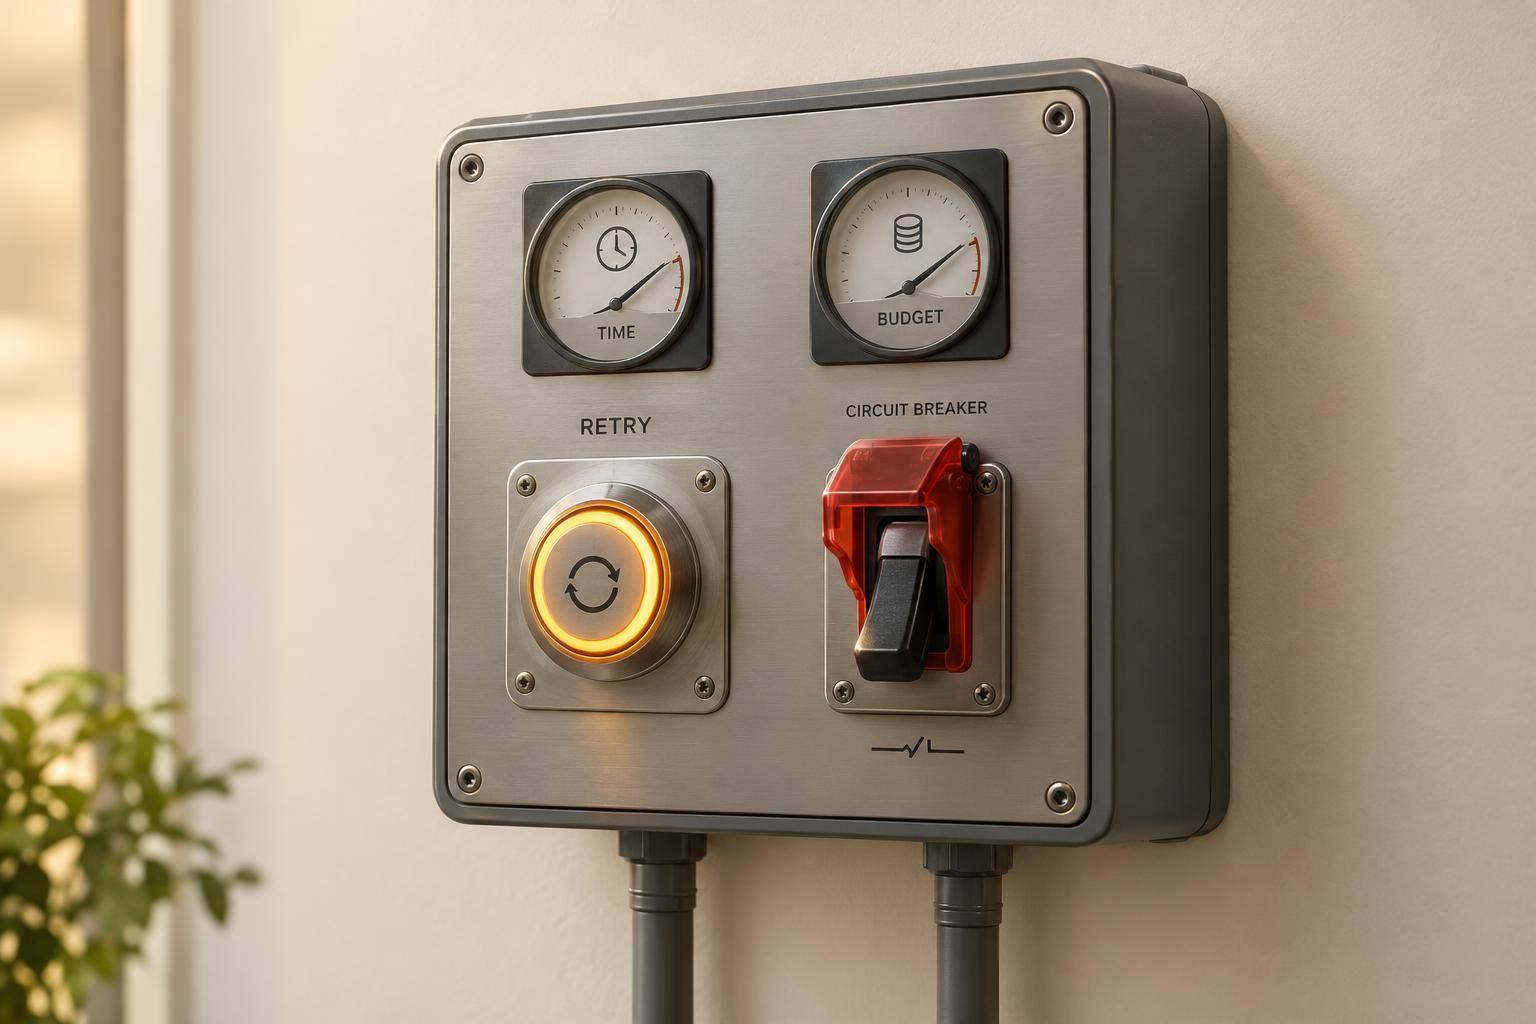
When to retry LLM API calls, when to open a circuit and how to switch fallbacks safely within shared deadlines and budgets.
Read more
Compare parallel voting and limited debate for multi-agent decisions—use voting for fixed outputs and bounded debate for disputes.
Read more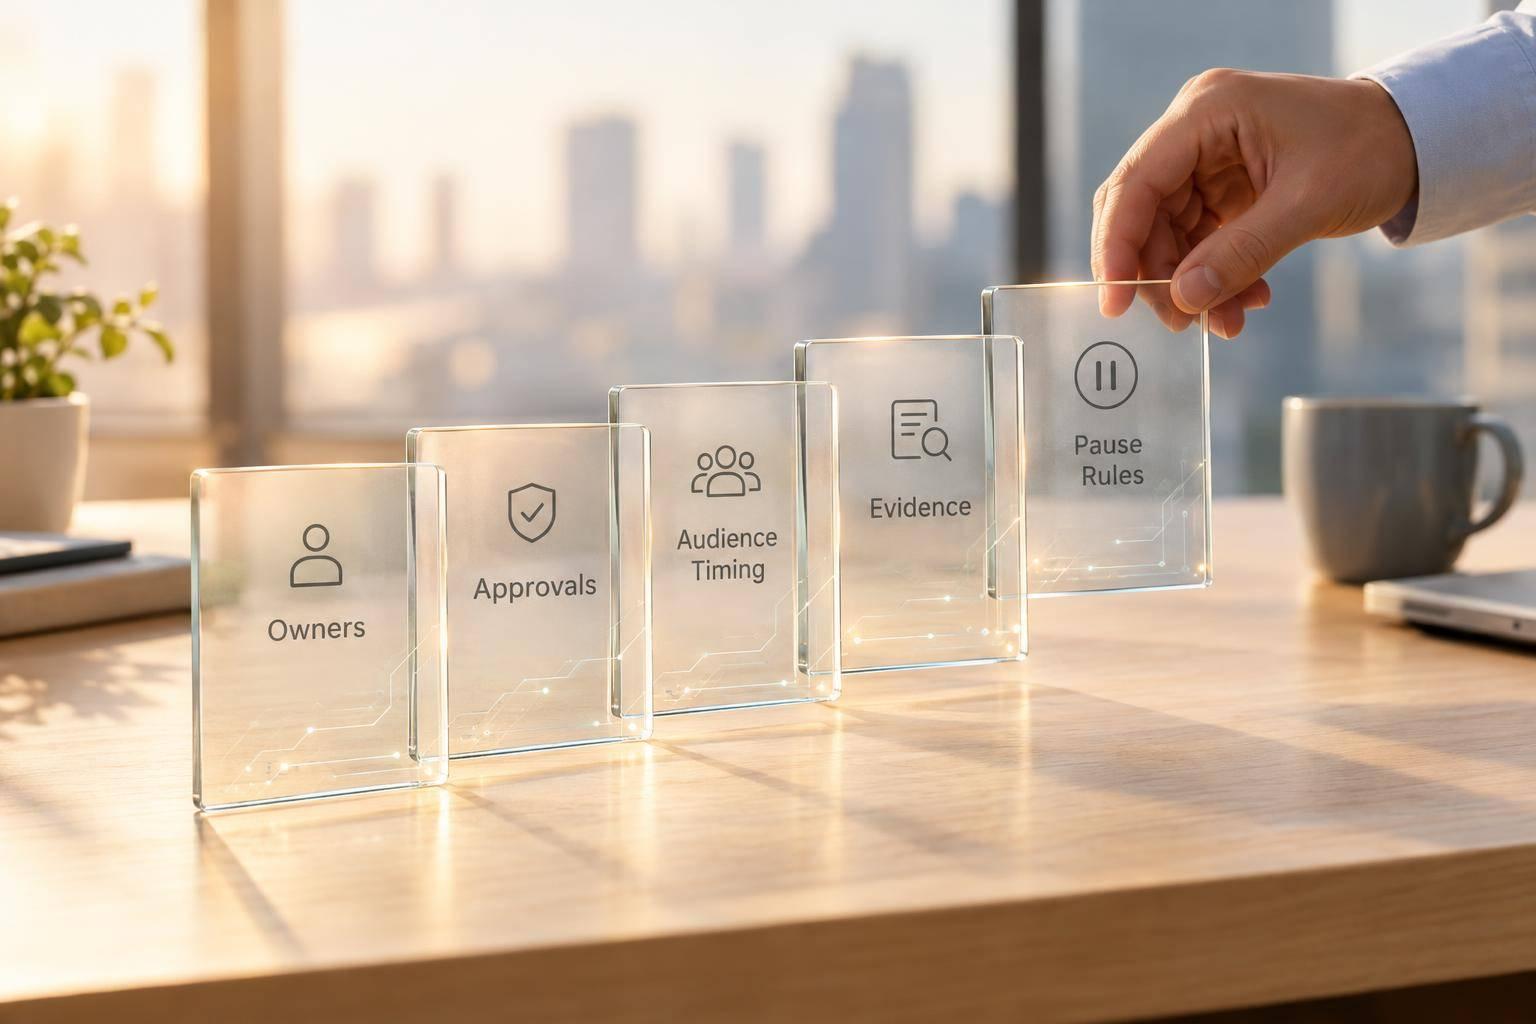
Staged messaging for AI pilots to rollout: owners, approvals, audience timing, evidence, and pause rules.
Read more
Measure verified results, enforce windowed progress checks and block further calls when AI agents show no measurable improvement.
Read more