Hybrid Cloud Failover: How It Works
Hybrid cloud failover keeps services running by automating detection, replication and recovery across on‑prem and cloud environments.
Read moreBlog posts in the Disaster Recovery category
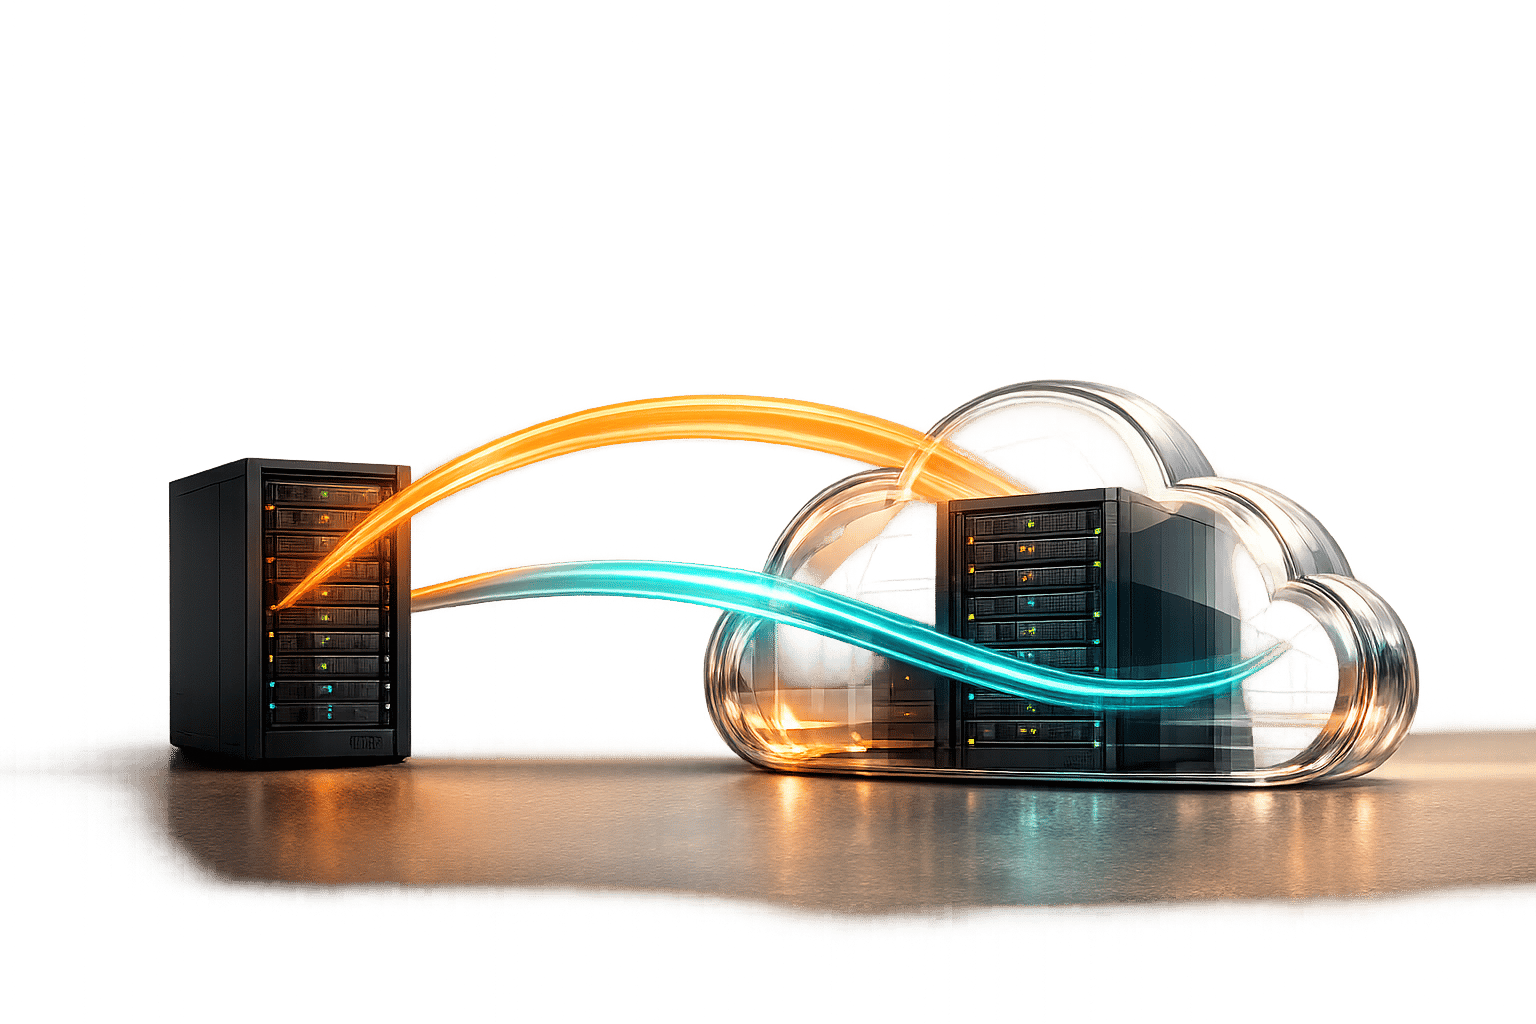
Hybrid cloud failover keeps services running by automating detection, replication and recovery across on‑prem and cloud environments.
Read more
Legal, data‑sovereignty and compliance risks from hybrid cloud backups, plus practical controls to cut fines and liability.
Read more
Scale and secure multi-cluster Kubernetes traffic with global load balancing, mTLS, service mesh and failover patterns.
Read more
Retry and backoff best practices for distributed systems: exponential backoff with jitter, retry budgets, idempotency, and circuit breakers.
Read more
AI boosts pipeline recovery with predictive detection and automated fixes, but requires human oversight for data gaps and novel faults.
Read more
Checklist of uptime, support, security, costs, termination and monitoring questions to review before signing a cloud SLA.
Read more
Compare AWS, Azure and Google storage tiers, fees and hidden costs to choose the most cost‑effective cloud storage.
Read more
Narrow SLA definitions and capped credits can leave your business exposed—use this checklist to verify uptime, support and enforcement.
Read more
Audit cloud vendor SLAs for uptime, latency, penalties and compliance using independent monitoring and enforceable metrics.
Read more
Practical tips to cut AWS Elastic Disaster Recovery costs: optimise disks, choose cheaper EBS types, right-size failover instances and monitor costs.
Read more
Plan, test and automate Kubernetes rollbacks across multiple clusters with GitOps, blue/green and canary strategies, metrics and versioned runbooks.
Read more
Compare thin, thick, hybrid, hyperconverged and cloud-adapted edge architectures to build resilient, low-latency systems while managing cost and complexity.
Read more